People Also Ask Optimization: How to Win Google’s PAA Boxes in 2026
Most SEO teams still treat people also ask optimization like it is 2021: write a short answer under a question heading, add FAQ schema, and hope Google extracts your text verbatim into the box. That playbook is not wrong, but it is now only half the story. In 2026, the most PAA answers are AI-synthesized from multiple sources rather than lifted from a single page, which changes what “winning” a PAA box means. This guide covers the full playbook — everything the standard guides teach, plus three tactics they consistently miss: a competitor PAA gap audit, an honest measurement framework for the zero-click era, and defensive PAA work that protects your brand. The result is a practical, repeatable people also ask optimization system you can run quarter after quarter — one that works whether answers are extracted verbatim or synthesized by AI. What People Also Ask Boxes Actually Do in 2026 The People Also Ask panel is a set of expandable question cards Google shows alongside search results. Each card carries a question related to the original query, and clicking one reveals an answer plus additional related questions — an endlessly expanding tree of follow-up queries. Google introduced the feature in 2015, and it has been one of the most common SERP features ever since. Two things make PAA uniquely valuable. First, multiple sources can win visibility for one keyword: different questions in the same box can cite different sites, so you do not need the top organic rank to appear. Second, the questions themselves are proven long-tail keywords and content ideas — Google builds PAA lists partly from query-log analysis, tracking the follow-up questions real searchers actually ask. That combination — multiple chances to be cited plus a free stream of validated long-tail questions — is why people also ask optimization deserves a dedicated slot in your SEO program. How Google Selects PAA Answers in 2026: The Big Shift Here is the update most older guides have not caught up with. The PAA box has quietly changed how it generates answers — and that changes what “winning” a PAA box means. In practice, this means the classic PAA mechanic — one page’s text pulled word-for-word with a clear source link — is no longer the typical outcome. Modern PAA answers behave like miniature AI Overviews tucked inside an accordion: they are synthesized across multiple sources. Independent measurements reported by FH SEO Hub put the share of AI-generated PAA answers at 97 to 100 percent as of late 2026, up from roughly 12 percent just fourteen months earlier. The goal of people also ask optimization in 2026 is therefore to become one of the cited sources feeding the synthesized answer, not to become the single extracted answer. This is closer to answer engine optimization than to the old PAA playbook. The good news: the same fundamentals win in both games — direct answers, question-based structure, genuine topical depth, and machine-readable formatting. In short, modern people also ask optimization is answer engine optimization with a SERP-feature lens: earn citations through clarity, structure, and authority. The PAA Answer-Block Formula Everything below follows one atomic unit that both traditional extraction and AI synthesis can parse cleanly: Question as the heading — an H2 or H3 phrased exactly or near-exactly the way real users ask it. Generic headings like “Common Questions” give the system nothing to match. The direct answer (40–60 words) — one tight paragraph that fully answers the question on its own, with no throat-clearing. This is the unit Google pulls. Supporting expansion — after the answer block, add context: an example, a data point, a short list, or a comparison. This feeds topical depth and keeps the page useful for human readers. A well-formed block looks like this: How long should a People Also Ask answer be? The most extractable PAA answers run between 40 and 60 words. That length gives Google a complete, self-contained answer to display while remaining short enough to quote cleanly. Writing the full answer before any expansion maximizes your chance of selection. Notice what that block does not do: it does not introduce the topic, hedge, or spend sentences on background before answering. Clarity beats creativity in answer extraction. Make this formula the default template for every answer your people also ask optimization program ships. The 7-Step People Also Ask Optimization Playbook Step 1: Harvest real PAA questions Start by searching your target keywords in Google and expanding every PAA question you see. For scale, use a dedicated mapping tool such as AlsoAsked, or filter by SERP features in Semrush or Ahrefs to see which boxes competitors occupy. Cross-reference against Google Search Console: queries already generating impressions for your pages are priority targets, a method Search Engine Land recommends for confirming real search intent. These harvested questions become the backlog for your people also ask optimization workflow: every item is real, searchable, and winnable. Step 2: Triage questions by winnability Not every question deserves an answer block. Score each candidate on three axes: relevance (does it match what your site genuinely has the authority to answer?), stability (questions appearing across multiple keyword searches tend to persist longer), and eligibility (the full answers Google selects typically come from pages that rank reasonably well for the question itself — if your page does not rank in roughly the top ten for the question, pick a different one or build that page’s authority first). Questions that score high on all three go into the production queue. This triage discipline is what separates professional people also ask optimization from casual FAQ-writing. Step 3: Match questions to content placement Resist the urge to dump every answer into one giant FAQ page. Integrated answer blocks outperform disconnected FAQ dumps because they sit inside semantically rich content. Map each question to the most relevant section of the most relevant page: pricing questions belong in pricing sections, timeline questions in process sections. This strengthens the page’s topical authority and gives the answer block
Author Bios for SEO: Trust Signals Google Actually Rewards
Learning author bio SEO best practices is one of the highest-leverage upgrades a website can make. A short paragraph about the person behind an article — their name, photo, credentials, and experience — quietly answers the first question both readers and Google’s quality systems ask: who wrote this, and why should I trust them? In this guide, you will learn exactly what to put in an author bio, how dedicated author pages multiply the effect, and the advanced trust signals most competitors still ignore. These author bio SEO best practices work for any niche and any site size. Why Author Bios Matter More Than Ever in 2026 Google’s search quality raters are explicitly trained to look for information about who created a page. The Search Quality Rater Guidelines mention E-E-A-T — Experience, Expertise, Authoritativeness, and Trustworthiness — well over a hundred times, and they instruct raters to check whether a page identifies its author along with their biography and credentials. Now, the guidelines are not a ranking algorithm. Google has also confirmed it does not rank sites on “author reputation” as a standalone factor. So why invest in author bios? Because they feed the signals that do matter: transparency, verifiable expertise, and entity clarity. A page with a named, credentialed author consistently outperforms an anonymous page on user trust metrics — longer dwell time, lower bounce rate, more return visits — and those behavioral patterns are exactly what modern ranking systems reward. That is the business case behind author bio SEO best practices: trust compounds into traffic. The shift became decisive when Google added the extra “E” for Experience to E-A-T in late 2022. Suddenly, it was not enough to know a topic; the content creator needed to have done the thing. The author bio is where that difference becomes visible. What Google Has Actually Said About Author Bios Separating Google’s official statements from industry interpretation matters for implementation: Google’s John Mueller has downplayed author bios as a direct ranking factor, describing them as more of a user-experience element. But he still advised publishers to show that their content creators “know what they’re talking about” and have relevant credentials. Meanwhile, Google’s own product decisions tell a louder story: Google’s news transparency guidelines list clear bylines and “information about authors” as core trust elements for news sources. Google Search Liaison Danny Sullivan has stressed using specific bylines instead of “By staff” for transparency. Google’s article structured data documentation recommends including the author’s URL, helping Google connect articles to people in its Knowledge Graph. Google has stated it knows which content belongs to the same author, and has tested knowledge panels for journalists highlighting their recent work. The pattern is unmistakable: Google keeps building infrastructure around authorship. Google’s own guidance on creating helpful, reliable, people-first content frames quality as three questions — who created it, how, and why — and the author bio is the clearest possible answer to the first one. Following author bio SEO best practices positions your site to benefit from all of it — present and future. The 8 Core Elements of Author Bio SEO Best Practices Before the advanced tactics, get the fundamentals right: these author bio SEO best practices should appear in every author bio on your site. 1. Write in the third person Third-person bios read as more authoritative than first-person ones. “Sarah is a technical SEO consultant” carries more weight than “I’m a technical SEO consultant,” even though Sarah wrote it herself. It reads as if someone else vouched for her. 2. Keep it short and scannable The industry norm is 50 to 100 words — three to five sentences. This is an elevator pitch, not a memoir. Save the full career story for the dedicated author page. 3. State the job title and function Specificity beats generality. “Technical SEO consultant specializing in JavaScript crawling” is far more credible than “marketing professional.” 4. Document relevant experience Include years in the field, notable employers, published works, speaking engagements, and media coverage. 5. Highlight expertise and credentials Degrees, certifications, licenses, and awards belong here — especially for YMYL topics (health, finance, legal) where bad advice can cause real harm. A finance article from a CPA and one from an anonymous blogger are not judged equally by readers. 6. Link to social and professional profiles LinkedIn is the heavyweight here, but X, industry associations, and a personal website all help. These outbound links let readers — and search engines — verify that the author is a real professional with a real public footprint. 7. Use a real, professional photo A genuine headshot humanizes the content. Use the same photo everywhere the author appears online; visual consistency reinforces entity recognition. 8. Add a touch of personality One personal line — an interest or a point of view — makes the bio memorable without undermining professionalism. Keep it brief. How Author Bio SEO Best Practices Strengthen E-E-A-T Each element maps to a dimension of Google’s E-E-A-T framework: E-E-A-T Dimension Bio Element That Feeds It Why It Matters Experience Years in field, past roles, “has done this” proof Added to the framework in 2022; first-hand experience is now a core quality signal Expertise Credentials, certifications, topical depth Critical for YMYL content where accuracy protects users Authoritativeness Media mentions, publications, speaking, social proof Shows the author is recognized by others in the field Trustworthiness Real name, real photo, verifiable profiles The foundation — without trust, the other three don’t register Unlike backlinks, which you must earn from others, every item in this table is an on-page move you can implement this week — which makes author bios the rare trust signal fully within your control. Dedicated Author Pages: The Step Most Sites Skip A bio snippet at the bottom of each article is the minimum. The real authority builder in any author bio SEO best practices playbook is a dedicated author page on its own URL — for example, yoursite.com/authors/jane-doe/ — linked from every byline. Why does the separate page
How to Build Topical Authority: Become the Go-To Source in Your Niche

Google increasingly rewards sites that demonstrate deep, connected coverage of a subject — the go-to source for a topic, not a random page that matches a keyword. This guide shows you how to build topical authority step by step: the honest definition, a 7-step system, a self-audit score, and how to measure it. No filler, no fake scores. What Topical Authority Really Means (Start With the Honest Version) Topical authority is the degree to which your site is recognized — by readers, peers, and search systems — as a consistently valuable, trustworthy source on a defined subject. The signs: deep coverage, original contributions, consistent focus, clear page relationships, positive reputation, and evidence people return to or cite your work. Here is the honesty part. Anyone teaching how to build topical authority should start with this: Google has never published a universal “topical authority score” the way Moz publishes Domain Authority. Google has documented a “topic authority” system for newsy queries — surfacing expert sources using signals like notability and original reporting — but that does not prove publishing 25 cluster pages triggers an identical site-wide mechanism for every blog. So treat “topical authority” as a practitioner framework, not a confirmed single ranking factor — per Google’s ranking-systems guidance, its systems work mainly at page level with some site-wide signals. The smart move: build topic depth as a consequence of serving your audience well, not as theater for an imagined score. Why Topical Depth Now Beats Raw Domain Authority The March 2026 core update changed the math for smaller sites: the winners shared one trait — narrow, deep topical coverage beat bloated domains stretching to rank for everything. The cautionary tale is just as clear. Generalist publishers that coasted on domain authority to rank for off-topic content got cut down hard — the widely reported traffic collapse of a major marketing publisher after years of “publish anything that ranks” is the textbook example. For a focused business, this is the best news in a decade. You no longer need to out-link a 500,000-page competitor — you need to know more about your specific topic and prove it. A regional plumber can now outrank a national media giant on a niche query because the plumber has the depth. That is the environment this playbook is built for. For a focused business, learning how to build topical authority is now the highest-leverage SEO investment available. How to Build Topical Authority: The 7-Step System Every site that has cracked how to build topical authority in 2026 uses some version of the same architecture. Here is the complete system, in the order that compounds. Step 1: Draw Your Topic Boundary The first decision when learning how to build topical authority is also the hardest: choosing what not to cover. A defensible topic sits where three circles overlap — audience demand, credible contribution, and strategic relevance. Write a one-sentence boundary statement: “We cover [subject] for [audience] so they can [outcome]. We do not cover [adjacent subjects] unless they change that outcome.” Topic discipline is the foundation everything else rests on. Step 2: Map Reader Jobs, Not Keyword Permutations List the decisions people make inside your topic in a spreadsheet, organized by job family: Understand, Choose, Plan, Implement, Troubleshoot, Measure, Maintain. Pull questions from People Also Ask, autocomplete, forums, and your inbox — customers ask things no tool shows you. Each distinct job becomes a candidate page; smaller questions become sections. This six-month editorial calendar is the engine of how to build topical authority. Step 3: Give Every URL Exactly One Job Before writing anything, assign each reader job to one URL and write a one-sentence responsibility for it: “This page is the site’s best answer for [reader] who needs to [job]; it does not own [neighboring job].” If two proposed pages cannot be distinguished without mentioning their target keywords, they are the same page. Merge them now. This prevents topical cannibalization: two of your own pages competing for one query split your relevance signals, so neither ranks as well as one complete page would. One job, one URL, no exceptions. Cannibalization is the most common reason teams stall when learning how to build topical authority — the repair playbook is covered later. Step 4: Publish the Pillar First, Then Clusters in Demand Order Your pillar page is the backbone of how to build topical authority that lasts: a 2,500–3,500-word resource covering the core topic broadly, answering the main question in the first hundred words, and linking to every supporting page. It should rank for the head term, and it is your most linkable asset. Then publish supporting pages in demand order — highest-demand subtopics first, so the cluster earns traffic while it grows. Each cluster page covers one subtopic thoroughly (1,200–2,000 words), links back to the pillar, and sideways to its closest siblings. A subtopic that cannot support 800 honest words is a section, not a page. Thin filler weakens the cluster. Step 5: Wire Internal Links Like Architecture, Not Decoration Internal links are the wiring diagram for how to build topical authority — how you tell Google “these pages are one body of expertise.” Most sites fail two ways: linking to the homepage instead of related posts, and dropping context-free links in the conclusion. The rules: every cluster page links to its pillar at least twice, with descriptive anchor text containing the pillar’s primary keyword. Place links inside the section that earned the citation — context around the link is what passes relevance. The pillar links down to every cluster; siblings link where one supplies the next decision. Sketch the map from memory before publishing. If you cannot sketch it, your plan for how to build topical authority is not finished yet. Step 6: Earn Depth With Information Gain A complete cluster is not the one with the most URLs. It is the one where every page contributes something beyond a competent summary: first-hand observation, original data, a worked example, a decision framework, a
Content Pruning: When Deleting Pages Actually Boosts Rankings
Every month your website gets a little bigger. Another blog post, another service page, another archive nobody visits. And every month, a little more of that content quietly stops pulling its weight. This content pruning seo guide shows you the counterintuitive fix experienced SEOs swear by: sometimes the fastest way to grow organic traffic is to shrink your site on purpose. Content pruning is not a deletion spree. It is a disciplined, data-driven process of deciding what every page deserves: keep, refresh, merge, hide from search, or remove for good. Done well, it raises site-wide quality, concentrates crawl budget, and eliminates silent ranking killers. Done carelessly, it nukes traffic overnight. This content pruning seo guide covers both sides. How This Content Pruning SEO Guide Is Different Most pruning guides hand you the same vague advice: audit your content, then keep, update, or delete. The hard part is the judgment calls in between. Instead of vague advice, you get a concrete 100-point scoring formula, exact rules for choosing between 301s, 410s, and noindex, a batch rollout method that protects traffic, and a section on pruning for AI search — the angle almost nobody covers. What Content Pruning Actually Is (And Isn’t) Content pruning is the systematic review of every indexed page on your website, followed by one of five deliberate actions per page: keep it as is, refresh it with better information, merge it with a stronger page, noindex it so it serves visitors without competing in search, or delete it and handle the URL properly. As this content pruning seo guide stresses, this is not a purge based on age. A five-year-old article that still earns backlinks and converts is an asset. A three-month-old post with zero impressions, zero links, and no strategic purpose is the real target. Age is context, never a verdict. It also isn’t a one-time project — content decays, intent shifts, and competitors publish better versions. Sites that prune every 6 to 12 months stay lean; sites that never prune accumulate clutter until the whole domain feels heavier than it should. Why Deleting Pages Can Raise Rankings: The Mechanics It feels wrong. How can removing content create more traffic? Because Google judges your entire site, not just individual pages, and every weak page drags that judgment down. Here is what this content pruning seo guide says actually changes when you prune. Site-quality signals tighten up Internal Google documentation that surfaced in recent years points to site-level quality metrics — how thematically focused a site is, and how far individual pages drift from its core topic. Remove off-topic, thin, or abandoned pages and you tighten that focus. The algorithm reads a smaller, sharper site as more authoritative. Your good pages don’t change; the company they keep does. Crawl budget concentrates on pages that matter Googlebot allocates limited crawl attention to every site. When hundreds of low-value URLs soak it up, your money pages get crawled less often. Pruning redirects that attention, so important pages get indexed faster and updates get picked up sooner — because the crawler stops wasting visits on pages nobody should see. Keyword cannibalization gets resolved This is the most common hidden win. Years of publishing leave sites with three or five pages all chasing nearly the same keyword. Google can’t decide which deserves to rank, so none rank well. Merging those competitors into one definitive page ends the internal fight — and consolidated pages routinely climb where the scattered ones stalled. Internal link equity stops leaking Every internal link passes authority to its target. When your site links generously to thin, outdated pages, that authority pours into pages that can’t convert it into rankings. After pruning, internal links point only at pages worth ranking, and the same total link equity does far more work. The 2026 Factor: Pruning for AI Search and LLM Citations Here is the angle most pruning guides miss: pruning now matters for how AI systems treat your site. AI Overviews and large language models build answers from sources they judge authoritative and focused. A sprawling site with 400 pages of mixed quality looks like a noisy library; a tight site with 120 excellent pages looks like an expert’s bookshelf. Guess which one gets cited. The mechanics favor focus twice over. AI systems lean on topical authority signals — the same site-focus metrics pruning improves. And when content is consolidated instead of scattered, AI systems find one comprehensive source to quote rather than fragments across six thin pages. If you want the full picture of how AI search decides what to cite, read our breakdown of how to rank in Google AI Overviews — then treat pruning as the foundation that strategy stands on. The Content Pruning Decision Matrix Every page gets exactly one fate. Run each URL through this content pruning seo guide matrix and commit to the outcome. Hesitation here is what turns pruning projects into six-month sagas. What the audit reveals Decision Before you act Healthy traffic, backlinks, current information, clear intent match Keep Confirm title, internal links, and next review date; change nothing else Topic still matters but facts are stale, depth is thin, or rankings slipped Refresh Rewrite substantially, update data and examples, keep the URL Two or more pages satisfy the same user intent Merge Pick the strongest URL, move the best material into it, redirect the rest Useful to visitors but adds nothing to search (login pages, thin archives, internal tools) Noindex Add noindex, keep the page live, remove from sitemap Obsolete, off-topic, zero traffic, zero links, no business purpose Delete Decide 301 vs 410 (see below), fix internal links first The noindex row is the one most site owners skip, and it’s often the smartest move. A page can be genuinely useful to logged-in users while actively harming your search profile. Noindex lets you have both. The 100-Point Content Pruning Scorecard “Evaluate each page” is where pruning guides go to die. So this content pruning seo guide gives you a scoring
How to Speed Up WordPress: A Practical Performance Guide
If you want to learn how to speed up WordPress without guessing, plugin-hopping, or breaking your site, this guide is for you. A slow WordPress site quietly drains your traffic, your Google rankings, and your revenue — most owners only notice when conversions have already slipped. Below you will find a practical 12-step performance plan, ordered by impact, plus three sections the top-ranking guides barely touch: no-plugin speed wins built into modern WordPress, WooCommerce-specific fixes, and a 30-minute diagnostic workflow to find your own bottleneck. Why a Slow WordPress Site Costs You Traffic, Rankings, and Revenue Speed is not a vanity metric. Around 47% of users expect a page to load within 2 seconds, and most abandon sites that take more than 3 seconds. Google confirmed page speed as a ranking signal, and its Core Web Vitals — Largest Contentful Paint (LCP) under 2.5 seconds, Interaction to Next Paint (INP) under 200ms, and Cumulative Layout Shift (CLS) under 0.1 — are direct ranking factors measured on real visitors. There is a newer dimension too: AI search tools like Google AI Overviews, ChatGPT, and Perplexity preferentially cite fast, well-structured sites. Research suggests sites loading under 2 seconds are significantly more likely to be referenced in AI-generated answers — which is why speed now matters for ranking in Google AI Overviews as well as classic search. Every extra second of load time costs roughly 4–8% in conversions, so performance work is a revenue investment, not a technical chore. How to Speed Up WordPress: The 12-Step Performance Plan Work through these steps in order. Each one builds on the last, and the first three alone typically fix the majority of slow WordPress sites — follow them in sequence and you will genuinely understand how to speed up WordPress instead of applying random tweaks. Step 1: Measure Your Speed Before Changing Anything The first rule of WordPress speed work: measure before you touch anything. Without a baseline, you cannot tell which fix worked. Run Google PageSpeed Insights on your homepage, your most-visited blog post, and your main landing page — results differ wildly between pages. Also check Google Search Console under Experience → Core Web Vitals for a site-wide view of which URLs pass or fail. Test logged out and in an incognito window, because the WordPress admin bar loads extra scripts that inflate your numbers. Step 2: Fix Hosting and PHP First No speed guide is honest if it skips hosting. Your server sets the ceiling for everything else: a slow host means a slow Time to First Byte (TTFB), and no plugin can fully hide it. Aim for TTFB under 200ms — anything above 600ms is a red flag. Look for managed WordPress hosting with PHP 8.3 or 8.4 (dramatically faster than PHP 7.x), server-level caching, NVMe SSD storage, and HTTP/3 support. Moving from budget shared hosting to quality managed hosting is routinely the highest-ROI single action, often improving response time by 400–600ms on its own. If you are budgeting for the upgrade, our breakdown of how much SEO costs puts performance work in the context of overall marketing spend. Step 3: Install One Caching Plugin — and Only One By default, WordPress rebuilds every page dynamically with PHP and database queries on each visit. A caching plugin stores a pre-built HTML copy and serves it instantly. Pick exactly one caching plugin — running two causes conflicts that can slow or break your site. Plugin What It Does Cost Best For WP Rocket Caching, minification, lazy loading, CDN integration Paid Non-technical owners who want one tool that just works LiteSpeed Cache Server-level caching, image optimization Free Sites on LiteSpeed servers — fastest free option W3 Total Cache Full caching stack, highly configurable Free Advanced users comfortable with manual setup FlyingPress Lightweight caching plus code optimization Paid Speed-focused sites wanting minimal overhead At minimum, enable page caching, browser caching, and GZIP or Brotli compression. Back up your site before enabling minify or combine features — some themes break when CSS or JavaScript is combined — and test thoroughly after each change. Step 4: Optimize and Compress Your Images Images typically account for 40–70% of total page weight, making them the number one cause of LCP failures on WordPress sites. A photo uploaded straight from a phone can be 4–8MB; a properly compressed web version should be under 200KB with no visible quality loss. The fix: resize images to their display size before uploading (content containers are usually 1200–1400px wide), then bulk-compress your existing library with ShortPixel, Smush, or Imagify and convert everything to WebP, which runs 25–35% smaller than JPEG. In our experience, disciplined image sizing is the habit that separates fast sites from slow ones in every how to speed up WordPress project we audit. Step 5: Switch to a Lightweight Theme Feature-heavy themes like Divi and Avada load sliders, animation libraries, and icon packs on every page whether you use them or not. Lightweight options with near-perfect Core Web Vitals out of the box include GeneratePress, Astra, Kadence, and block-based themes. Step 6: Minify CSS and JavaScript, Defer Non-Critical Scripts Every CSS and JavaScript file is a request your visitor’s browser must download, and render-blocking scripts delay LCP because the page cannot paint until they finish. Minification strips whitespace and comments, typically shrinking files by 20–40%. Your caching plugin (or Autoptimize, free) handles this automatically. Then defer or async-load anything not needed for the first paint: analytics, chat widgets, and social embeds should never block rendering. Check PageSpeed Insights for the “Eliminate render-blocking resources” warning and fix each flagged file. Step 7: Add a CDN A content delivery network stores copies of your static files — images, CSS, JavaScript — on servers worldwide, so visitors download from the nearest location instead of your origin server. Cloudflare’s free tier covers most small business sites and adds DDoS protection automatically; BunnyCDN is a fast, ultra-affordable alternative for image-heavy sites. Enable Cloudflare’s Auto Minify for HTML, CSS, and JS as a bonus optimization
Mobile SEO Checklist: Winning Google’s Mobile-First Index in 2026
Google no longer asks whether your site works on mobile — it assumes the mobile version is your site. Since the mobile-first index rollout completed, Google’s smartphone crawler is the primary version it uses to evaluate your content, relevance, and user experience. This mobile SEO checklist 2026 gives you 12 concrete steps to audit and fix your mobile presence, based on what actually moves rankings this year: Core Web Vitals measured on real devices, strict mobile–desktop content parity, speed on slow networks, and a mobile experience users actually enjoy. Over 58% of global web traffic now comes from mobile devices, and on many B2C sites the figure is far higher. If your mobile experience is an afterthought, you are not just losing conversions — you are handing your competitors the rankings. Work through the mobile SEO checklist 2026 below in order; each step builds on the last. Why Mobile SEO Is Non-Negotiable in 2026 Mobile-first indexing changed the fundamental question of SEO. Google used to crawl your desktop site and treat the mobile version as a bonus. Today it crawls your site with a smartphone user-agent, indexes what that crawler sees, and ranks you accordingly. A site whose desktop version is flawless but whose mobile version hides content, blocks resources, or loads in nine seconds will underperform — on both mobile and desktop results, which is why every item on the mobile SEO checklist 2026 matters. The business case is just as stark. Mobile users bounce faster, convert less readily, and have zero patience for pinching, zooming, or waiting. A one-second improvement in mobile load time can lift conversions measurably, while intrusive pop-ups and broken tap targets silently kill the traffic your content earned. Mobile SEO in 2026 is therefore not a technical side-project; it is the main event, and the mobile SEO checklist 2026 treats it that way. How Google’s Mobile-First Index Actually Works Understanding the mechanism makes the checklist easier to follow. When Google discovers your URL, it fetches it as Googlebot Smartphone — a mobile user-agent with a mobile viewport. The HTML, structured data, and resources returned in that response are what get indexed. If your mobile page serves less content than the desktop page, drops your schema markup, or noindexes itself, Google indexes the lesser version. Google’s own documentation on mobile-first indexing best practices is the authoritative reference, and it is worth reading alongside this guide. Two consequences follow. First, parity is everything: the mobile and desktop versions must carry the same primary content, the same structured data, the same metadata, and the same internal links. Second, mobile page experience is a ranking input: Core Web Vitals measured from real mobile users (the Chrome User Experience Report, or CrUX) feed directly into how Google assesses your pages. The checklist below is organized around exactly these two pillars, plus the UX layer that connects them to revenue — the three pillars the mobile SEO checklist 2026 is organized around. The Mobile SEO Checklist 2026: 12 Steps That Actually Move Rankings Every item on this mobile SEO checklist 2026 is something you can verify today with free tools. Run through them in sequence and fix what fails before moving on — the mobile SEO checklist 2026 rewards completion, not cherry-picking. 1. Confirm your mobile-first indexing status Step one of any mobile SEO checklist 2026 is verification, not assumption. Open Google Search Console, paste a key URL into URL Inspection, and check the “Crawled as” line — it should read Googlebot smartphone. Then open the Page indexing and Mobile Usability reports and clear every error: viewport misconfiguration, content wider than the screen, text too small to read, and clickable elements too close together. These are not cosmetic warnings; they are Google telling you exactly why a page is held back. 2. Go responsive — or annotate your separate mobile site properly Responsive design remains Google’s recommended configuration, and for good reason: one URL, one HTML, no redirect chains, no annotation headaches. If you still run a separate mobile site (m.example.com), you are maintaining two codebases and doubling your QA surface. Should you keep it, the setup must be exact: every desktop page needs a rel=”alternate” pointing at its mobile twin, every mobile page needs a rel=”canonical” pointing back at the desktop version, and mobile redirects must be single-hop and fast. Redirect latency hits mobile users hardest, because every extra round-trip happens on a slower connection. Most teams that migrate from m-dot to responsive see their mobile maintenance burden — and their mobile error counts — drop sharply. 3. Pass Core Web Vitals on mobile, not just on desktop Core Web Vitals are Google’s page-experience metrics, and on mobile the thresholds are unforgiving: LCP (Largest Contentful Paint) under 2.5 seconds, INP (Interaction to Next Paint) under 200 milliseconds, and CLS (Cumulative Layout Shift) under 0.1. Crucially, Google judges you on field data — real measurements from real Chrome users on real phones — not on what your developer’s laptop reports. That is why the mobile SEO checklist 2026 starts with measurement, not guesses: pull your CrUX data in Search Console’s Core Web Vitals report, then use PageSpeed Insights to see both lab and field numbers for the exact URLs that matter. Fix the biggest offender first. LCP on mobile is usually an oversized hero image or a slow server response; INP suffers when heavy JavaScript blocks the main thread during taps and scrolls; CLS spikes when images lack dimensions, ads inject late, or web fonts swap aggressively. Set explicit width and height on every image, reserve space for ad slots, and use font-display: swap with fallback fonts that match closely. 4. Optimize for slow networks, not just fast phones Your office Wi-Fi is not your user’s reality. Test every key template throttled to a mid-tier 4G connection — PageSpeed Insights and WebPageTest both offer this — and set a hard page-weight budget of 1.2–1.5 MB for typical content pages. The mobile SEO checklist 2026 rule of thumb: if it
Duplicate Content: How to Find It and Fix It With Canonicals

This duplicate content fix guide walks you through the full cleanup: how to find duplicate pages hiding on your site, how to choose between canonical tags, 301 redirects, and noindex, and how to stop duplicates from coming back. Duplicate content is one of the most misunderstood problems in SEO. Many site owners either panic about a “penalty” that does not exist or ignore duplication while it quietly drains their rankings. This duplicate content fix guide covers everything the standard advice covers, plus the parts most articles skip: what to do when Google ignores your canonical, how to handle scraped content, and how clean canonicalization helps you win citations in AI search. What Duplicate Content Really Means (And the “Penalty” Myth) Duplicate content is substantive blocks of identical or near-identical text appearing on more than one URL — inside your own site (internal duplicates) or across domains (external duplicates). Internal duplication is far more common, and it is the one you can fix. Let us clear up the biggest myth first: Google does not have a “duplicate content penalty” in the way most people imagine. Google’s own engineers have said repeatedly that duplicate content does not trigger a manual penalty. Instead, Google picks one URL as the canonical version and ranks that one. The danger is not punishment — it is that Google may pick the wrong version. That is exactly why every good duplicate content fix guide treats this as a control problem, not a punishment problem. Your job is to tell Google clearly which URL deserves the ranking credit. The 3 Real Ways Duplicate Content Costs You Rankings When identical content lives at multiple URLs, three things go wrong — usually silently. Any duplicate content fix guide worth following starts here: understanding exactly how duplication costs you rankings before you touch a single canonical tag. 1. Google picks the wrong canonical When Google sees the same page at /shoes, /shoes/, /shoes?sort=price, and /shoes?page=1, it chooses one to index — and that choice does not always match yours. A thin parameter variant can outrank your main page despite having far weaker internal-link signals. Spotting these cases early is one reason this duplicate content fix guide puts canonical inspection before content rewrites. 2. Link equity gets split External backlinks pointing to /shoes and /shoes/ count as two separate URLs unless you consolidate them. Authority that should flow into one strong page gets scattered across clones — a bigger loss than most teams expect. 3. Crawl budget gets wasted Googlebot’s crawl budget is limited. On large catalogs with layered navigation, bots can spend most of their quota crawling thousands of parameterized variants of the same pages, leaving new and important pages under-crawled and slow to index. Where Duplicate Content Comes From: 7 Sources Most Sites Miss Most duplication is not someone copying your text — it is your own site generating multiple URLs for the same content, and this duplicate content fix guide will help you find every source: URL parameters: tracking tags (?utm_source=…), filters, and sorts (?sort=price, ?color=blue) create near-identical pages. HTTP vs HTTPS and www vs non-www: without redirects, these are four separate sites to Google. Trailing slash variants: /page and /page/ are different URLs. Product variants: separate URLs for every color or size of the same product. Pagination: /blog/page/2/, /blog/page/3/ with near-identical templates. Printer-friendly and session URLs: print versions, session IDs, and AMP variants of the same page. Syndicated and manufacturer content: the same product description or article republished on multiple domains. On WordPress, tag archives, author archives, and attachment pages add the same problem quietly — see the WordPress checklist below. How to Find Duplicate Content: A 4-Step Audit Finding duplicates is step two of this duplicate content fix guide. Run these four checks: Step 1: Read the Google Search Console Pages report Open the Pages (indexing) report in Google Search Console and look at two buckets: “Duplicate, Google chose different canonical than user” and “Duplicate without user-selected canonical.” These are the exact URLs Google already considers duplicates — your fix list starts here. Step 2: Search your own site Take a distinctive sentence from an important page, put it in quotation marks, and run a site:yourdomain.com “exact sentence” search. If the same text shows up on multiple URLs, you have found a duplicate cluster. Step 3: Crawl the site Run Screaming Frog — its “Near Duplicates” report surfaces high-similarity URLs — or an Ahrefs/Semrush site audit. For smaller sites, Siteliner gives a fast free check. Crawlers also expose duplicate titles, duplicate meta descriptions, and redirect chains in the same pass, which is why this duplicate content fix guide recommends a crawl as the backbone of every audit. Step 4: Scan for parameter URLs Filter your crawl for URLs containing ?sort=, ?filter=, ?utm_, ?session=, and similar parameters. Decide which of these provide unique search value and which merely reproduce existing content. Your Duplicate Content Fix Guide Toolkit: 301 vs Canonical vs Noindex There are exactly three fixes, and choosing the right one is what this duplicate content fix guide is built around. They are not interchangeable: Fix What it says Use it when 301 redirect “Go to this other URL.” The duplicate has no reason to exist as its own page: trailing-slash variants, http→https, old URLs after a migration, deleted products. Canonical tag “This is the preferred version among similar URLs.” The duplicate must stay live for users (filters, variants, tracking URLs, paginated pages) but only one version should rank. Noindex “Do not index this page at all.” The page must work for people but should never appear in search: internal search results, thank-you pages, admin pages. 301s pass effectively all link equity to the destination and remove duplicates from the index. Canonical tags consolidate signals too, but they are a hint, not a directive — Google can ignore them if your other signals disagree. Noindex is the strongest exclusion signal, but the page will never rank, so use it only where ranking is never wanted. Getting
Redirect Chains: How to Find and Fix Them Before Rankings Drop
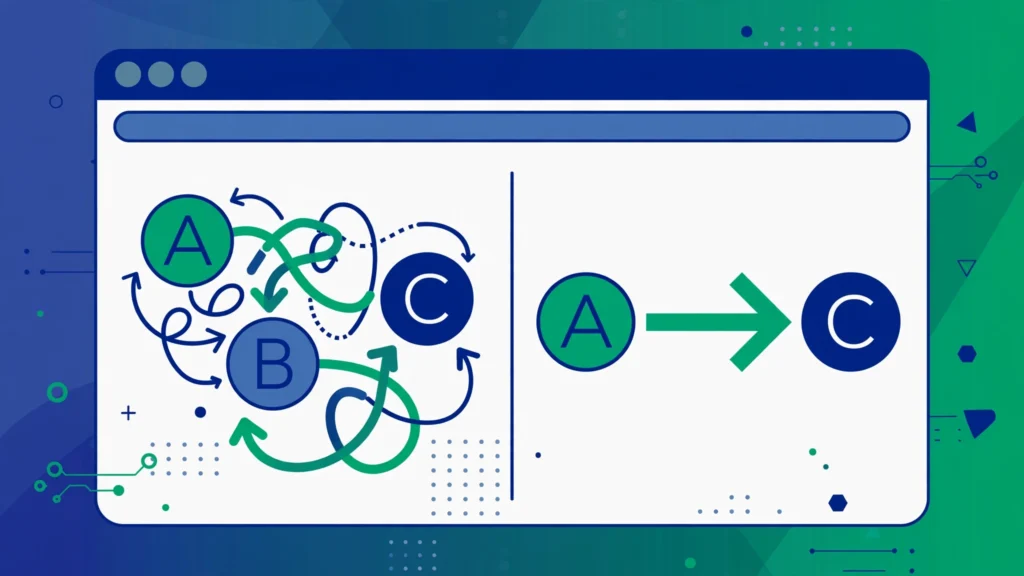
A redirect chain fix SEO cleanup is one of the cheapest technical wins available. A chain forms when URL A redirects to URL B, which redirects to URL C, which finally returns a page. Every hop adds latency, burns crawl budget, and gives ranking signals one more chance to leak. Once you can see the chains, flattening them is usually a config edit away. This guide shows you how to find chains with free and paid tools, fix them step by step, prioritize which ones matter, and stop them from coming back — including the hidden traps standard audits miss. Consider it a complete redirect chain fix SEO checklist you can run on any site. What Is a Redirect Chain? A redirect chain is two or more consecutive HTTP redirects where the original URL points to an intermediate URL that itself redirects, repeating until the request finally resolves to a live page. Picture it like this: Single hop (healthy): /old-page → 301 → /new-page → 200. One redirect, then the page loads. Chain (needs fixing): /old-page → 301 → /older-page → 301 → /new-page → 200. Two hops before the page loads. Long chain (urgent): four or five hops before the final 200. Googlebot may give up following after about five. A chain is different from a redirect loop, which never ends: URL A sends you to B, B sends you back to A, and the browser gives up with ERR_TOO_MANY_REDIRECTS. Chains tax your site; loops break the page entirely. Knowing which one you are dealing with shapes the whole redirect chain fix SEO response. How Redirect Chains Form (Nobody Builds Them on Purpose) Chains accumulate quietly over years of changes because nobody reconciles old rules. The most common origins a redirect chain fix SEO review uncovers: Stacked migrations. You moved /blog/post → /articles/post last year, then /articles/ → /learn/ this year. Nobody updated the first rule, so the original URL now takes two hops. HTTP-to-HTTPS plus www normalization. http://example.com → https://example.com → https://www.example.com resolves in two hops when a single rule could handle it. Trailing-slash and case rules layered on top of content redirects, each firing in sequence. CMS plugins fighting server config. A WordPress redirect plugin and an Nginx or Apache rule can both fire on the same request, producing a hop you cannot see from either tool alone. CDN or reverse-proxy rules added at the edge without knowledge of origin redirects. Tracking and affiliate wrappers that bounce through measurement domains before reaching the real landing page. Link shorteners run twice. Shortening a URL that already redirects adds a hop every time it is used. The pattern never changes: a redirect points at a URL that is itself a redirect. A proper redirect chain fix SEO process rewrites the source rule to skip the middlemen. Why Redirect Chains Hurt SEO A single, clean 301 is harmless — the standard tool for signaling a permanent move. The damage comes from stacking them. Measuring that damage is the first job of any redirect chain fix SEO cleanup: Crawl budget. Each hop is a separate request a crawler must make and follow. On a large site, thousands of multi-hop chains mean Googlebot spends its crawl allowance chasing redirects instead of discovering real content. Google’s own crawl budget documentation warns site owners to avoid long redirect chains. Speed and Core Web Vitals. Every hop is a fresh DNS lookup, TCP/TLS handshake, and round trip before the page even starts loading. Lighthouse fails pages with two or more redirects, and each one can delay a resource by hundreds of milliseconds — a visible stall on mobile networks. Indexing delay. A page at the end of a chain can still rank, but the redirect signals slow how quickly Google processes it — and every hop gives the crawler another chance to move on. Signal fragility. Google says 301s pass PageRank without loss, but that assumes the redirect actually resolves. Long chains raise the odds that a hop times out, a server strips headers, or a temporary code sneaks in — any of which can stop signals flowing through. Indexing ambiguity. Long or inconsistent chains make it harder for Google to settle on the canonical URL. If a chain lands on a 404 or soft 404, the equity dead-ends entirely. One published audit of a B2B site found 847 redirect chains, some seven hops long, alongside a 34 percent organic traffic decline. After collapsing 127 priority chains, the crawl rate rose 23 percent in three weeks and largest contentful paint dropped 620 milliseconds. With AI Overviews pulling from crawled content, crawl efficiency matters more than ever — see our guide on how to rank in Google AI Overviews for why being reliably crawlable is now table stakes. Redirect Status Codes, Decoded Knowing which code to use is half the battle in a redirect chain fix SEO project: Code Name Permanent? Use it for 301 Moved Permanently Yes Permanent moves, migrations, canonical consolidation; the SEO default 308 Permanent Redirect Yes Permanent moves where the HTTP method must survive (APIs, forms) 302 Found No Genuinely temporary moves, A/B tests, short promos 307 Temporary Redirect No Temporary moves that must preserve the request method Meta refresh HTML-level n/a Avoid: slow, fragile, weak SEO signal JS redirect Client-side n/a Avoid on SEO-critical paths; bots may not execute it Two rules prevent most chains: use 301 (or 308) for anything permanent, and never use a temporary code for a permanent move — a misused 302 keeps stale URLs indexed. See Google’s guidance on 301 redirects for how permanent redirects should behave. How to Find Redirect Chains You cannot fix what you cannot see. Detection is the first half of any redirect chain fix SEO engagement, from a quick spot-check to a full inventory: Single-URL header trace. Run curl -sIL https://example.com/old-page and read the HTTP status lines and Location headers. Each 3xx before the final 200 is one hop — the fastest free method, and it never lies. Browser DevTools.
404 Pages and SEO: How to Handle Broken URLs the Right Way
Learning how to fix 404 errors SEO the right way is one of the highest-leverage technical SEO skills you can build. Broken URLs silently drain link equity, waste crawl budget, and frustrate visitors — yet most site owners either panic over harmless 404s or ignore the dangerous ones. This guide gives you the full playbook: what 404s actually do to rankings, how to find every broken URL on your site, a 90-minute audit routine, and the exact fixes (301 redirects, 410s, custom 404 pages) that protect your traffic. What Is a 404 Error, Really? A 404 error is your server telling a browser or crawler: “this URL doesn’t map to any content right now.” It happens when a page is deleted, a URL is renamed without a redirect, someone mistypes a link, or the URL never existed. Not all “not found” signals are the same, and mixing them up causes the real SEO damage: Hard 404: The server returns a proper HTTP 404 status code. This is the correct response for content that is genuinely gone. Soft 404: The page looks like an error to humans but the server returns a 200 OK status. Google detects these algorithmically and treats them like 404s — except they confuse crawlers and waste crawl budget. Soft 404s are often worse than real 404s. 410 Gone: A stronger signal meaning “this URL is gone and never coming back.” Google treats 410 similarly to 404 but typically removes the URL from its index faster. For JavaScript-heavy sites, there’s a fourth trap: single-page apps that render a “not found” view without changing the HTTP status, producing mass soft 404s. If you run an SPA, make sure your server returns a genuine 404 for dead routes. Do 404 Errors Actually Hurt Your SEO? Short answer: 404s are not a direct ranking factor. Google’s official documentation has said for years that normal 404s are part of a healthy web, and a few broken URLs won’t drag down your other pages: the fact that some URLs return 404 does not affect how your remaining URLs perform in search results. However, Google’s Gary Illyes added a key nuance: 404s split into URLs that should return content (an important page accidentally deleted) and URLs that shouldn’t — the first bucket is where the real damage lives. When 404s hit URLs that still matter, the indirect impacts are serious: Lost link equity: Backlinks pointing at a dead URL are wasted — the authority those links built mostly evaporates unless you redirect the URL. Lost indexation and rankings: Google drops 404 URLs from its index over time. You stop ranking for every query that URL used to capture. Crawl budget waste: Mostly a large-site problem: when Googlebot spends its crawl allocation re-checking junk URLs, fresh content gets discovered more slowly. Broken user journeys: Visitors who hit dead ends leave, try a competitor, or abandon their task — you lose the lead or sale either way. The takeaway: don’t fear 404s in general — fear the important ones. Internalizing that distinction is the first step in learning how to fix 404 errors SEO the right way. How to Find 404 Errors on Your Website The first step in how to fix 404 errors SEO audits get right is detection: you can’t fix what you can’t see, and most 404s hide in places you never check. A solid detection workflow mixes four sources: 1. Google Search Console Start here — it shows what Google actually tried to crawl. In Indexing → Pages, open “Not found (404)” and “Soft 404,” export the URLs, and check referring pages. Cross-reference with the Links report: 404s with external backlinks are your top priority. 2. Crawl your own site A crawler shows which of your own links point to dead pages. Screaming Frog, Sitebulb, or Ahrefs Site Audit flag every 4xx response — check the “inlinks” tab to find the source pages, and fix those links alongside any redirects. Enable JS rendering for JavaScript-heavy sites. 3. Server and CDN logs On larger sites, logs show what Googlebot and real users actually request. Filter by 404/410 status, count hits per URL, and match against referrers — even a simple CSV export from your host reveals your worst offenders. 4. Analytics and CMS dashboards If your 404 template has a unique page title, build a GA4 report filtered by it to find the dead URLs visitors hit most. Many WordPress plugins, Shopify, and CDNs like Cloudflare log 404 hits automatically. The 90-Minute 404 Audit Routine (Do This Quarterly) Fixing 404s at scale comes down to process, not heroics. Here’s a repeatable routine you can run in about 90 minutes every quarter — or after any redesign, migration, or bulk content pruning: Export (15 min): Pull the “Not found (404)” and “Soft 404” lists from Search Console, plus a fresh Screaming Frog crawl filtered to 4xx. Merge into one spreadsheet. Enrich (20 min): Add three columns per URL: monthly organic clicks, referring domains, and inlink count. This turns a scary list into a ranked priority queue. Triage (15 min): Sort by impact and assign each URL to a bucket — Redirect (301), Restore, Leave as 404/410, or Fix the link. Fix (30 min): Implement redirects, repair internal links, and publish or improve your custom 404 page if you haven’t yet. Verify (10 min): Re-crawl the fixed URLs to confirm correct status codes (301 → 200, not chains), then use GSC’s “Validate Fix” so Google re-checks your work. Set a calendar reminder. Sites that audit 404s on a schedule almost never get surprised by them. How to Fix 404 Errors SEO the Right Way: 5 Fixes That Matter Once your audit list is triaged, match each URL to the right fix — using the wrong one is worse than doing nothing. Fix 1: Restore the page If an important page was deleted by accident, just bring it back. Check whether the URL drove traffic or had backlinks before assuming it’s disposable. Fix 2:
XML Sitemap Optimization: 7 Mistakes Hurting Your Indexing
Your XML sitemap is the single most direct line of communication between your website and Googlebot. Yet most sites treat it as a set-and-forget file that their CMS plugin generated once, years ago. That neglect has a cost: every noindex page, dead redirect, and bloated URL dump inside your sitemap is a wasted crawl request you personally invited. This guide to xml sitemap optimization walks through the seven mistakes that quietly hurt your indexing, plus a 20-minute audit workflow that fixes them. Before we start, set expectations correctly. As Google’s Gary Illyes confirmed, a sitemap is not a direct ranking factor — there is no ranking bonus for having one. Its job is discovery and crawl efficiency: helping Google find the right pages faster, especially on large sites, new sites, and sites with weak internal linking. Faster, more complete crawling gives your pages a better chance of being evaluated and indexed. Ranking still depends on relevance, quality, and authority. Proper xml sitemap optimization buys you coverage and speed, not positions. Mistake #1: Including Noindex Pages in the Sitemap This is the single most common sitemap error in the wild, and it creates a direct contradiction. Your sitemap says “please crawl and index this,” while the page’s noindex tag says “please don’t index me.” Google notices the conflict and flags it in Search Console. How does this happen? A CMS generates the sitemap once, dumping in every URL it knows about. Later, someone noindexes a thin category page, a staging copy, or a PPC landing page — and nobody revisits the sitemap. The result is a file arguing with itself. The fix: audit your sitemap against your noindex directives. Crawl your sitemap URLs with a free tool like Screaming Frog (500-URL free tier), export the list, and filter for any page carrying a noindex tag or an X-Robots-Tag: noindex header. Remove every one of them. The rule is simple: if a page should not appear in Google’s search results, it should not appear in your sitemap. Mistake #2: Listing Redirects, 404s, and Other Non-200 URLs Every URL in your sitemap should return a clean HTTP 200. Redirected URLs (301/302), broken pages (404), and server errors (5xx) waste crawl budget and confuse the indexer. When Googlebot follows a sitemap into a dead end, it learns to trust your sitemap less — and a sitemap Google distrusts gets processed slower and less completely. Stale URLs accumulate silently. You delete a product line, restructure a blog category, or migrate to a new URL pattern, and the old addresses linger in a static sitemap file for months. One audit we recommend in our technical SEO work routinely finds 10-20% of sitemap URLs returning non-200 statuses on sites that have never cleaned their sitemaps. The fix: during xml sitemap optimization, export every sitemap URL and check its status code. Keep only the 200s. For redirects, list the destination URL instead of the redirect. And switch to a dynamically generated sitemap — WordPress plugins like Rank Math and Yoast regenerate the file automatically whenever content is published, updated, or removed, so this class of problem never recurs. Mistake #3: Including URLs Blocked by robots.txt This mistake is Mistake #1’s louder cousin. Your sitemap invites Googlebot in; your robots.txt file turns it away at the door. Search Console reports these as “Blocked by robots.txt” in the indexing report, and the conflict erodes Google’s trust in both files. The fix: cross-reference the two files. Every URL in your sitemap must be crawlable according to robots.txt. If a section of the site is deliberately blocked (admin areas, internal search, staging), it has no business in the sitemap. Run both files through your head at the same time — or better, automate the check in your deployment pipeline so a new Disallow rule never silently conflicts with your sitemap. Mistake #4: Ignoring Size Limits in XML Sitemap Optimization Google’s documented limits are generous: 50,000 URLs and 50 MB uncompressed per sitemap file. Almost nobody hits them — but that doesn’t mean size doesn’t matter. In practice, a single sitemap file stuffed with tens of thousands of URLs gets processed less reliably than several smaller, logically grouped files. Mixed-quality mega-sitemaps are the ones where Google partially processes the file and quietly ignores the tail. The fix: split by content type and business value. Create separate sitemaps for pages, posts, products, categories, and media, and reference them all from a sitemap index file. This segmentation does more than respect protocol limits — it lets you read Search Console’s per-sitemap stats and see exactly which section of your site has an indexing problem. A blog sitemap showing 40% indexation while your product sitemap shows 95% tells you where to look. You can never get that signal from one giant file. Mistake #5: Fake or Missing Lastmod Dates The <lastmod> tag tells Google when a page actually changed, and Google uses it to decide whether re-crawling is worthwhile. Two failure modes are everywhere: No lastmod at all. Some generators omit it, leaving Google to guess whether content changed. Dishonest lastmod. Setting every lastmod to the build time, request time, or today’s date “to force recrawls.” Google’s Gary Illyes has said Google checks whether the sitemap changed before reprocessing — but it also learns patterns. A site that cries wolf on every URL trains Google to ignore its freshness signals entirely. The fix: tie lastmod to real content events — the actual publish or meaningful-update timestamp of the page. Don’t bump it for typo fixes or template changes. Honest lastmod data is one of the cheapest crawl-efficiency wins in xml sitemap optimization, because it concentrates Googlebot’s attention on pages that genuinely changed. Mistake #6: Dumping Every URL the CMS Generates Tag archives with three posts. Author pages for one-time guest writers. Thin filter combinations like ?color=red&size=m&sort=price. Printer-friendly versions. Search-result pages. The CMS happily generates all of these, and a lazy sitemap includes all of them. The damage is dilution. Your sitemap has a finite amount