Crawl budget is Google’s term for the set of URLs it can and wants to crawl on your site. For most sites it is not a problem worth worrying about. For large or fast-changing sites, and for sites that have accidentally generated huge numbers of near-duplicate URLs, it can decide how quickly new pages are found. This guide to crawl budget optimization explains when it matters, how to check your own site with free Search Console data, and the fixes Google itself recommends, with a worked example.
Key takeaways
- Google’s guide is aimed at sites with roughly 1 million or more unique pages that change about weekly, sites with 10,000 or more pages that change daily, or sites with many URLs in “Discovered, currently not indexed”. Google calls these figures a rough estimate.
- If new pages are crawled the same day they are published, Google says keeping your sitemap current and checking the Page Indexing report is adequate.
- Crawl budget combines crawl capacity (what your server can handle) and crawl demand (how much Google wants your content).
- The biggest practical lever is URL inventory: consolidate duplicates, block unimportant URL spaces, and remove soft 404s and long redirect chains.
- Do not use noindex to save crawl budget, because Google still has to request the page to see the tag.
What crawl budget actually is
Google defines crawl budget as the set of URLs that Google can and wants to crawl. It is the combination of two things.
- Crawl capacity limit: how much time Googlebot can spend on your host without harming it. The limit rises when your site responds quickly and reliably, and falls when it slows down or returns 5xx or 429 responses. It is shared across Google’s crawlers.
- Crawl demand: how much Google wants to crawl, driven by the perceived size of your URL inventory, the popularity of your pages, and how stale its copies are. Size, update frequency, quality and relevance all play into it.
Two consequences follow. A fast, healthy server does not guarantee more crawling if demand is low. And a site with enormous numbers of low-value URLs can hold up crawling of the pages you care about, because Google may spend time on URLs it later decides are not worth indexing.
Does it matter for your site?
| Situation | Likely verdict |
|---|---|
| A few hundred pages, new posts are crawled and indexed within a day or two | Not a crawl budget problem. Keep the sitemap current and watch the Page Indexing report. |
| Around 10,000 or more pages with daily changes, such as a catalog or marketplace | Worth reviewing, per Google’s own guide. |
| Hundreds of thousands of URLs from filters, sorting and parameters | Likely wasteful. Fix URL inventory first. |
| Many URLs labelled “Discovered, currently not indexed” | Investigate. Could be crawl capacity, demand, or quality. |
| Frequent 5xx errors or timeouts in Crawl Stats | Fix server stability first. It limits capacity. |
Remember that your page count is what Google can discover, not what your CMS dashboard shows. A shop with a modest product range can expose a very large number of URLs once color, size, price and sort options combine across categories.
How to check your site in Search Console
Start with data you can get for free.
- Open the Crawl Stats report (Settings in Search Console). It shows total crawl requests, total download size and average response time. It is available only for root-level properties (a Domain property or a root-level URL-prefix property), and Google describes it as aimed at advanced users, noting that sites with fewer than a thousand pages generally do not need it.
- Read the breakdowns. Crawl responses show the share of OK, redirect, not found and server error responses. File type shows what is being fetched. Crawl purpose separates discovery of new URLs from refreshes of known ones. Click an entry for example URLs.
- Check host status. It covers robots.txt fetching, DNS resolution and server connectivity over the past 90 days. An unreachable robots.txt can make Google slow or stop crawling until it gets a usable response.
- Open the Page Indexing report and note how many URLs sit in “Discovered, currently not indexed” and “Crawled, currently not indexed”.
- Spot-check with URL Inspection. If it shows “Hostload exceeded”, Google suggests adding server resources.
Keep the report’s limits in mind. It is not a complete log, numbers can differ slightly from your server logs, redirect chains count each hop as a separate request, and example URLs are representative only. For precise answers on a large site, your server logs are the better source.
Worked example: reading the numbers
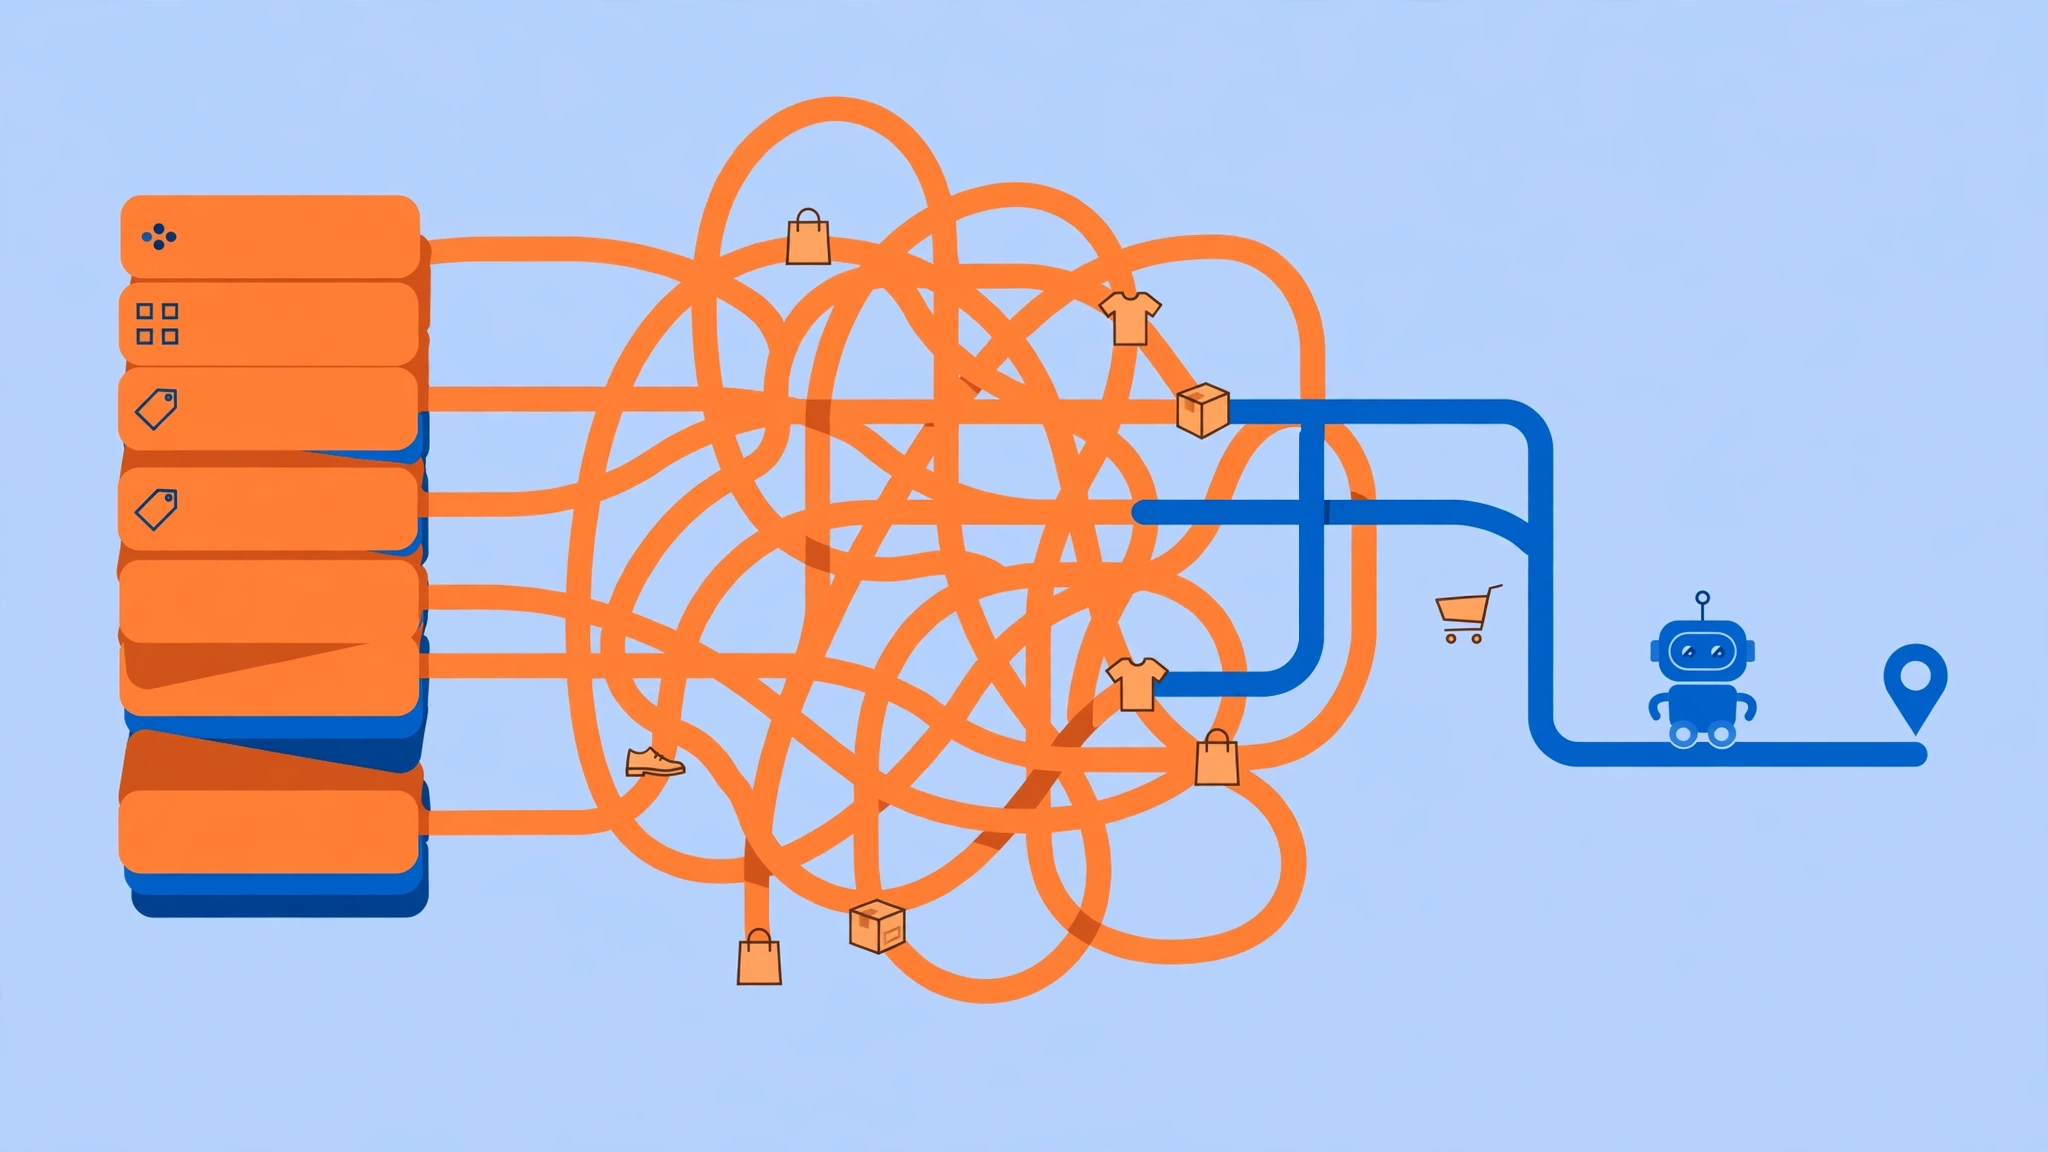
Example scenario: a hypothetical online store has about 8,000 real product and category pages, but Crawl Stats shows that most requests go to URLs containing sort and filter parameters, with a noticeable share of redirects and not-found responses. New products take weeks to appear in Search, and the Page Indexing report shows a large pile of “Discovered, currently not indexed”.
- Diagnosis: Google is spending its attention on a huge, low-value URL space, and a chunk of requests hit redirects and dead pages.
- First fix: block parameter-based filter and sort URLs in robots.txt, while keeping the unfiltered category pages and the product pages crawlable.
- Second fix: remove redirecting, noindexed and dead URLs from the sitemap, and flatten redirect chains to a single hop.
- Third fix: make removed products return 404 or 410, and make sure empty filter combinations return 404 instead of a friendly “no results” page with a 200 status.
- Measure: re-check Crawl Stats after a few weeks. Expect the share of responses that are OK and refer to real pages to rise, and expect new products to be discovered sooner.
The scenario and its observations are invented to show the method. Real timelines depend on your site.
The fixes that matter
1. Manage faceted navigation and parameter URLs
Google’s faceted navigation guidance says filters can generate near-endless URLs, and that crawling them can overload servers and slow discovery of useful new pages. Its default recommendation is to block them unless they truly need to appear in Search. If you do not need the filtered URLs indexed, disallow the parameter-based URLs in robots.txt while leaving an unfiltered listing page that shows all items, plus the item pages, crawlable. If you do want some filtered pages in Search, rel=”canonical” to a less-filtered version may reduce crawl volume over time, and rel=”nofollow” on links works only if every link to the URL carries it. Google describes both as less effective in the long term than blocking. For indexable facets, use the standard & separator, keep filter order consistent, and return 404 for combinations with no results, duplicates and nonsensical combinations.
2. Consolidate duplicate content
Google advises focusing crawling on unique content rather than unique URLs. Merge or canonicalize duplicates and retire the variants you never want shown.
3. Return the right status for removed pages
For permanently removed pages, return 404 or 410. Google calls a 404 a strong signal not to crawl that URL again. Blocked URLs, by contrast, stay in the crawl queue longer and are recrawled once the block is removed.
4. Eliminate soft 404s
A soft 404 is a page that shows an error or empty message but returns a 200 status. Google notes these keep being crawled and waste budget. Make real errors return real error codes.
5. Keep sitemaps clean and lastmod honest
Include the content you want crawled and use lastmod for updated content. Google uses lastmod only when it is consistently and verifiably accurate. See our guide to XML sitemap optimization for the full audit routine.
6. Avoid long redirect chains
Google lists long redirect chains as something that hurts crawling. Point each old URL straight to its final destination. Our redirect chain guide shows how to find them.
7. Make pages efficient to load
Improve server response times and resource loading, and support HTTP caching. A 304 Not Modified response lets Google reuse its cached copy and saves bandwidth.
What not to do
- Do not use noindex to save crawl budget. Google still requests the page, then drops it after seeing the directive, which wastes crawl time.
- Do not expect robots.txt to reallocate budget. Google says blocking URLs does not shift the freed budget to other pages unless your site is already at its crawl capacity limit. The benefit of blocking is that junk URLs stop being processed, not that good pages get extra visits automatically.
- Do not rely on a sitemap alone. Submitting one is a hint, not a guarantee of crawling.
A four-week plan
- Week 1, measure: record Crawl Stats totals, response mix and host status, plus the Page Indexing counts.
- Week 2, inventory: list the URL patterns being crawled most (parameters, archives, internal search) and decide which deserve to be indexed.
- Week 3, clean up: robots.txt rules for junk patterns, sitemap cleanup, redirect chains flattened, soft 404s fixed.
- Week 4, verify: test key URLs with URL Inspection, then re-check Crawl Stats over the following weeks.
Also note that Google’s capacity limit is shared across its crawlers, and other automated crawlers can add load of their own. If bot traffic is a concern, see our llms.txt guide, and for AI answer features see how to rank in Google AI Overviews.
Common mistakes
- Optimizing crawl budget on a small site whose real problem is thin content or weak links.
- Blocking a URL pattern in robots.txt that contains pages you want indexed.
- Using noindex as a crawl-saving measure.
- Leaving redirecting and dead URLs in the sitemap.
- Treating Crawl Stats as an exact log.
Frequently asked questions
Does crawl budget affect rankings?
Not as a ranking factor. It matters because a page that is not crawled cannot be indexed, and a page that is not indexed cannot rank.
How do I increase my crawl budget?
Google says to add server resources if URL Inspection shows “Hostload exceeded”, and to improve content quality, since crawl demand reflects popularity, user value and uniqueness.
Should small sites worry?
Usually not. Google says that if pages are crawled the day they are published, a current sitemap and a look at the Page Indexing report are adequate.
Sources
- Google: Optimize your crawl budget
- Google: Managing crawling of faceted navigation URLs
- Search Console Help: Crawl Stats report
- Google Search Central: Build and submit a sitemap
If you would like a second opinion on crawl waste, you can contact SSA Agency.